Applied ML · Generative AI
My contribution
I developed a collection of LLM projects, including FinBERT pruning and knowledge distillation with saved evaluation results.
Applied ML collection
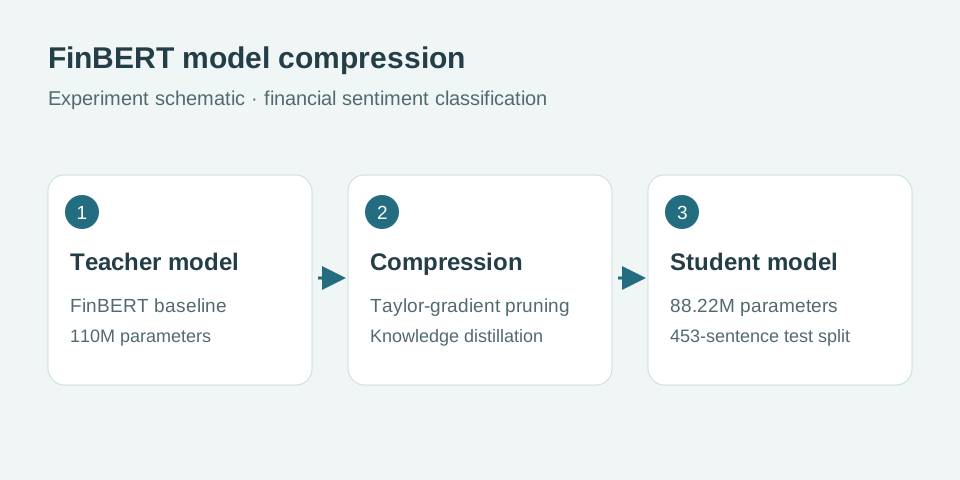
FinBERT compression: distillation recovers accuracy to within 0.7 points of the baseline after layer dropping; absolute scores are optimistic because the test split likely overlaps the baseline's fine-tuning data.
Problem
Exploring retrieval-augmented generation, structured data access, and model compression through implemented pipelines and evaluations.
System
A collection of nine projects at varying levels of completeness, including a Medical RAG Assistant (LangChain, ChromaDB, conversational memory), a two-stage Enterprise NL-to-SQL pipeline, LoRA/QLoRA parameter-efficient fine-tuning, and a full compression pipeline (Taylor-gradient pruning plus knowledge distillation) applied to a FinBERT financial-sentiment classifier.
Result
On a 453-sentence Financial PhraseBank test split, layer dropping alone cuts the 97.6% baseline accuracy sharply, to 61.8%; knowledge distillation recovers nearly all of it, landing within 0.7 points of baseline while keeping the ~19% reduction in parameters and model size. The baseline (ProsusAI/finbert) was fine-tuned on the Financial PhraseBank, so most test sentences were probably seen in training: the absolute accuracies are optimistic, and the finding is the relative effect of the compression steps.
Scope
The reported metrics apply to the FinBERT compression experiment. Other projects in the collection have different implementation and evaluation coverage; they are not all deployed or fully evaluated systems.